


Generate More is a Helsinki-based AEO and AI SEO agency for Nordic and international B2B software companies, founded in 2024 by Lari Numminen. This study tracks how Finnish news media respond to AI companies' bots. The first measurement was made in February 2024, the second in October 2026, and we will repeat it with the same method in 2027.
Key findings
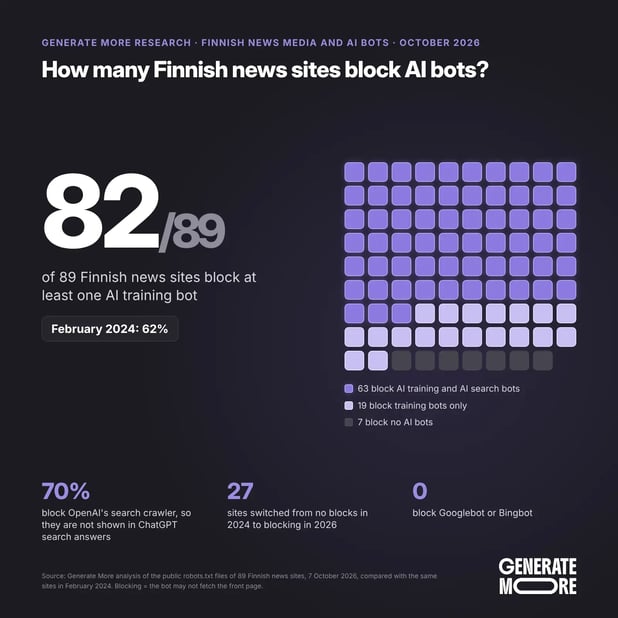
In October 2026 we went back to the same 99 Finnish news sites we checked in February 2024. Of these, 89 are still online at their own address, so the comparison covers those 89.
| Measure (89 comparable news sites) | February 2024 | October 2026 |
|---|---|---|
| Blocks at least one of the eight bots tracked in 2024 | 55 (62%) | 82 (92%) |
| Blocks OpenAI's search crawler (OAI-SearchBot) | not measured | 62 (70%) |
| Blocks at least one AI search crawler (OAI-SearchBot, PerplexityBot or Claude-SearchBot) | not measured | 63 (71%) |
| Blocks training bots but leaves search crawlers open | not measured | 19 |
| Blocks no AI bots | 34 | 7 |
| Blocks Googlebot or Bingbot | 0 | 0 |
Three things stand out. Blocking AI bots has gone from the exception to the norm, and only seven sites leave every AI bot free to crawl. Most sites now also block the bots that ChatGPT, Perplexity and Claude use to find sources for their answers. Publishers have split into two camps, and the line often follows the media group.
Training bot or search bot: why the difference matters
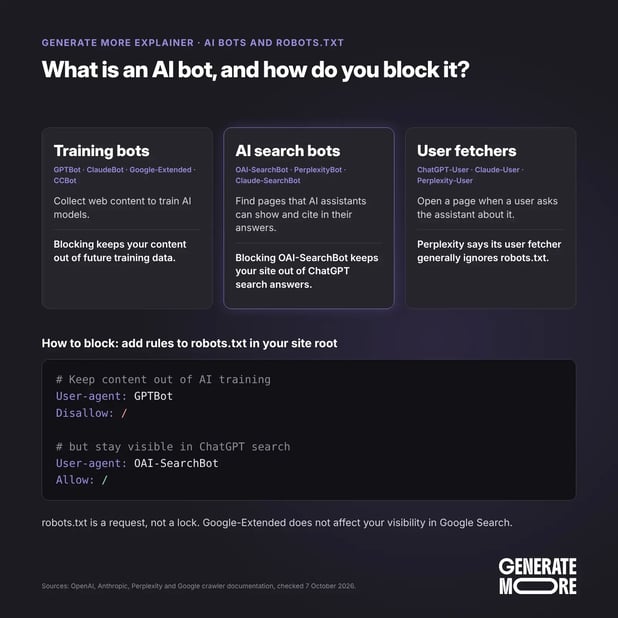
In 2024 the question was simpler. News sites mainly decided whether their content could be used to train AI models. AI companies now run separate bots for training and for search, and blocking each one has a different consequence.
OpenAI's crawler documentation says that disallowing GPTBot means a site's content should not be used to train its models. According to the same page, sites that block OAI-SearchBot are not shown in ChatGPT search answers. In Anthropic's guidance, ClaudeBot collects content for training, while blocking Claude-SearchBot can reduce a site's visibility in search results. Perplexity says in its documentation that PerplexityBot surfaces sites in search results and is not used to train AI models.
Google works differently. Google-Extended controls whether content may be used to train Gemini models and to ground answers in Gemini apps. According to Google's documentation, it does not affect a site's inclusion in Google Search. That is why none of the news sites has lost its Google visibility, even though 82 of them block Google-Extended.
Two camps: block everything, or block training only
Most sites have closed the door to both training and search bots. All 29 Keskisuomalainen titles in the study also block OpenAI's and Perplexity's search crawlers. Alma Media's sites, Helsingin Sanomat, Ilta-Sanomat, Aamulehti, Turun Sanomat and Hufvudstadsbladet go further and block Claude's search crawler as well. Their articles should therefore not appear as sources in ChatGPT search answers.
The second group blocks training only. It includes Yle, Kaleva's newspapers, Ilkka-Pohjalainen and its local papers, A-lehdet's Apu and Eeva, Maaseudun Tulevaisuus, Koneviesti and the magazines ET-lehti, Gloria and Kodin Kuvalehti. A-lehdet makes the choice most visibly: its robots.txt names the search and user bots of OpenAI, Claude and Perplexity separately and closes only a few directories to them, while the training bots are blocked from the whole site.
Who changed course
In February 2024, 34 of the 89 sites blocked no AI bots. Today 27 of them do. The change has happened at the level of whole media groups: all seven Kaleva newspapers, Turun Sanomat's local papers, four Otava magazines, four Hilla Group newspapers, HSS Media's Swedish-language papers and Viestimedia's titles have all started blocking.
The most visible single change is Yle, the Finnish public broadcaster. In 2024 its robots.txt had no instructions for AI bots. Today it blocks the whole site for 38 named bots, including GPTBot, ChatGPT-User, ClaudeBot and Google-Extended. Yle's file does not name the search crawlers of OpenAI, Perplexity or Claude, so the same general rules apply to them as to other search engines.
None of the sites that blocked bots in 2024 has removed its blocks.
Who blocks nothing
Seven sites block no AI bots at all: Ålandstidningen, Åbo Underrättelser, Pietarsaaren Sanomat, Kansan Uutiset, Hymy, MTV Uutiset and Nya Åland. Among Swedish-language outlets, five of eight now block training bots, compared with three in 2024.
Bot by bot
The table shows how many of the 89 sites block each bot from their front page in October 2026.
| Bot | Company and purpose | Blocked by |
|---|---|---|
| GPTBot | OpenAI, training | 82 |
| Google-Extended | Google, Gemini training | 82 |
| CCBot | Common Crawl, open web dataset | 82 |
| ChatGPT-User | OpenAI, user-requested fetches | 78 |
| ClaudeBot | Anthropic, training | 67 |
| PerplexityBot | Perplexity, search | 63 |
| OAI-SearchBot | OpenAI, ChatGPT search | 62 |
| Applebot-Extended | Apple, training | 33 |
| Claude-SearchBot | Anthropic, search | 28 |
| Googlebot and Bingbot | Google and Bing search | 0 |
Newer bots such as Claude-SearchBot and Applebot-Extended are still missing from many files. The gap suggests that many publishers update their lists rarely, so how complete a block list is depends on when it was last reviewed.
What this means for companies
When ChatGPT or Perplexity answers a question about a Finnish company or industry, it cannot use as a source a news site that has blocked its search crawler. Seven in ten of the news sites we studied have done so. Other content is left to become the source for the answer.
For a company this can be an opportunity. When many news sites are missing from AI search sources, clear and current information on the company's own website is more often available as the basis for an answer. I explain how to get there in how to get visibility on ChatGPT.
Method
Sample. The same 99 Finnish news and magazine sites as in the February 2024 study. The media group labels are from the 2024 study.
Data. Each site's public robots.txt file was downloaded on 7 October 2026. The files were read with the robots.txt parser in Python's standard library, which tells whether each bot may fetch the site's front page.
Comparison. The 2024 comparison uses the same eight bots as in 2024: CCBot, ChatGPT-User, GPTBot, Google-Extended, Omgilibot, FacebookBot, Amazonbot and anthropic-ai. The 2024 article reported that 58% of all 100 sites blocked them. This comparison covers only the 89 sites still online, and 62% of those blocked bots in 2024.
Excluded. Ten sites were left out. Four have merged into another paper or redirect to one, five no longer respond, and vaasa.fi is now the City of Vaasa's website.
Limits. robots.txt is a request, not a technical block. The study does not measure bot blocking done by firewalls or content delivery networks. Perplexity says its user fetcher generally ignores robots.txt rules.
Update log
- February 2024: first measurement, 100 sites and eight bots.
- October 2026: second measurement, 89 comparable sites and 19 bots, including AI search crawlers.
- Next measurement: 2027.
Frequently asked questions
Finnish news media and AI bots FAQ
How many Finnish news sites block AI bots?
In October 2026, 82 of the 89 sites studied (92%) blocked at least one AI training bot. In February 2024 the share was 62%.
Do Finnish news sites appear in ChatGPT answers?
Most do not. 62 of 89 sites block OpenAI's search crawler, and according to OpenAI such sites are not shown in ChatGPT search answers.
Do the news sites block Google?
No. None of them blocks Googlebot or Bingbot. Blocking Google-Extended does not affect visibility in Google Search, according to Google.
What is the difference between a training bot and a search bot?
A training bot collects content to train AI models. A search bot fetches pages that an AI service uses and links to as sources in its answers.
How do you block an AI bot?
Add the bot's name on a User-agent line in the robots.txt file at your site root, followed by Disallow: /. robots.txt is a request, and not every bot follows it.
Can I use the figures?
Yes, with a link to this page as the source.
